
Inference Platform: Deploy AI models in Production | Pipeshift
Rate this Tool
Average Score
Total Votes
Select your score (1-10):
Detail Information
What
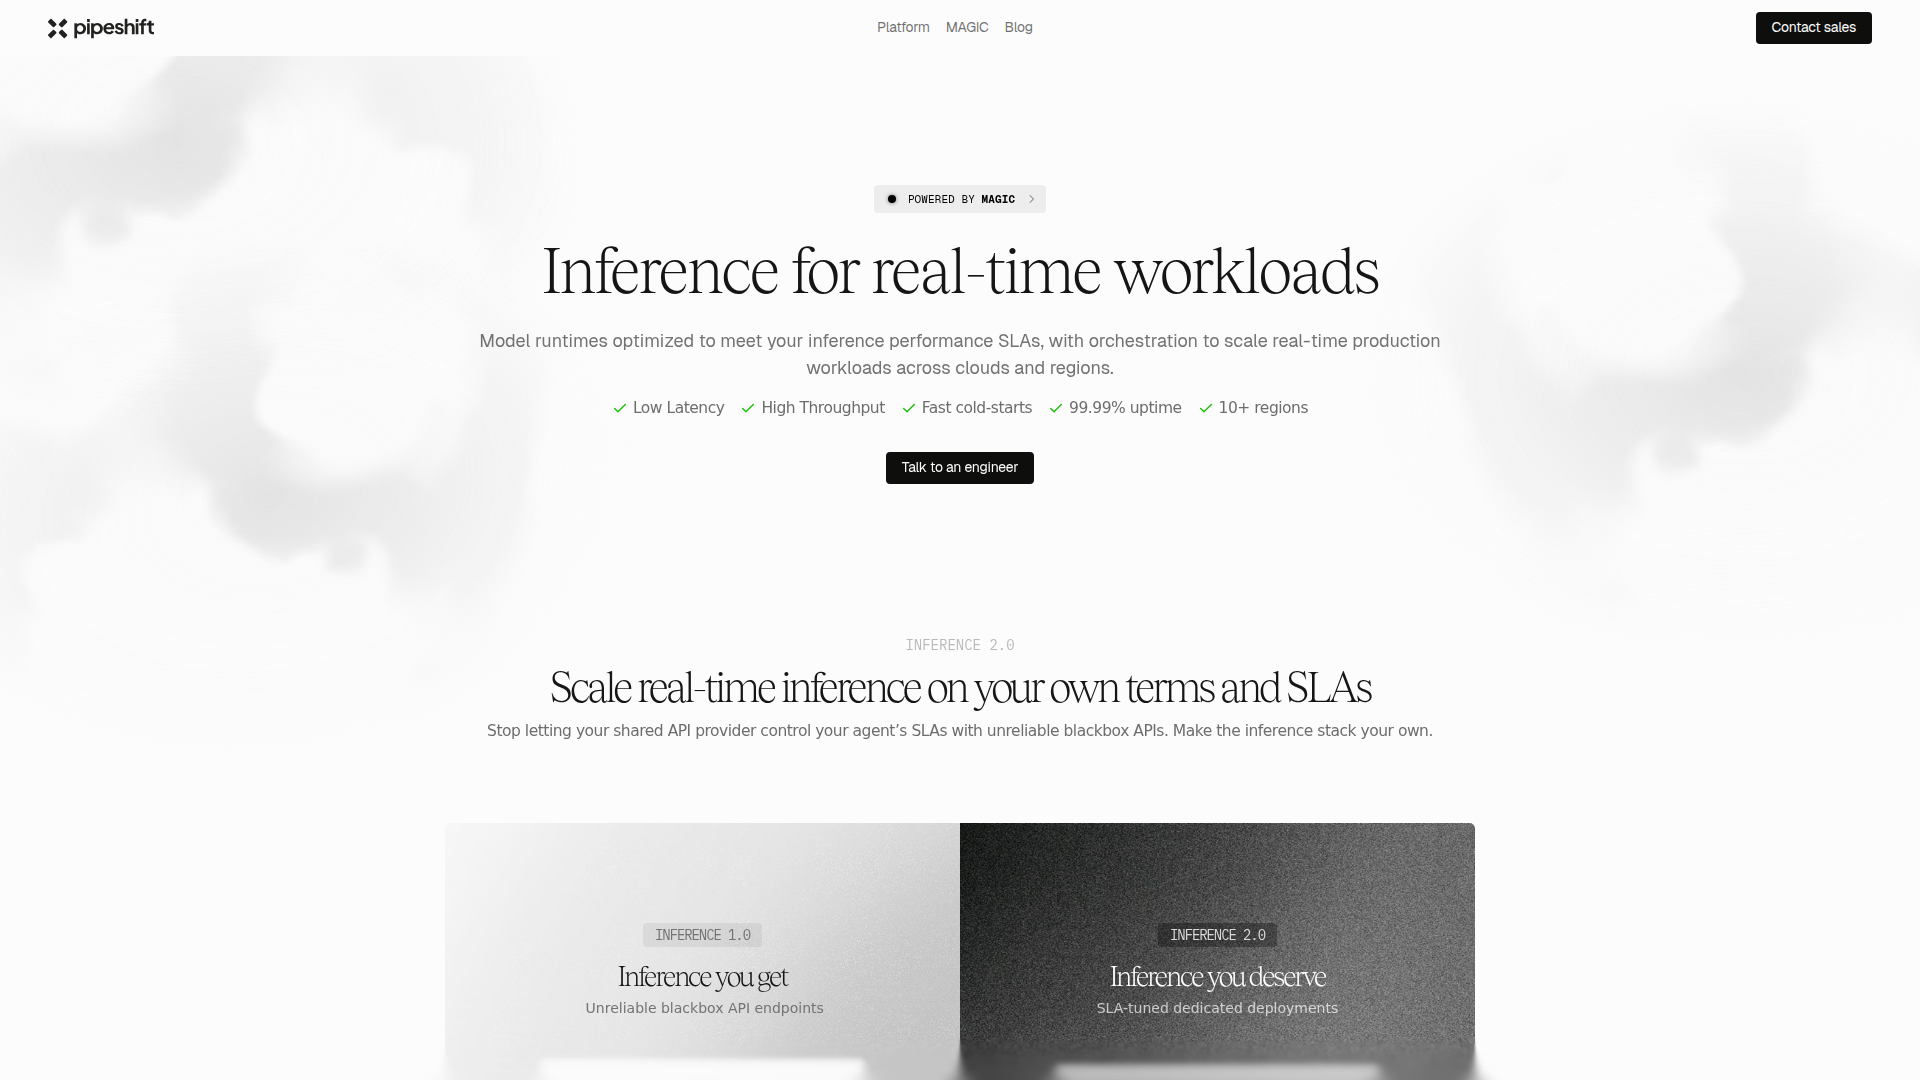
Pipeshift is an inference platform for deploying AI models in production, with a focus on real-time workloads that need low latency, high throughput, fast cold starts, and high uptime. It serves teams building AI products and agents that rely on open-source, custom, or fine-tuned models and need more control than shared API providers typically offer.
The platform appears positioned as dedicated, single-tenant inference infrastructure for production use rather than a general-purpose model API marketplace. Its core workflow is to let teams choose a model, apply performance presets through its MAGIC framework, define inference SLAs, and deploy API endpoints that can scale across clouds, regions, or self-hosted environments.
Features
- Single-tenant dedicated deployments: Provides dedicated model deployments instead of shared black-box APIs, which helps teams pursue stricter privacy, reliability, and performance control.
- SLA-based inference orchestration: Lets users define SLA targets and uses orchestration, auto-scaling, and scheduling to maintain real-time production performance under changing demand.
- MAGIC inference optimization framework: Compiles workload-specific inference pipelines with techniques such as KV caching, custom kernels, speculative execution, model parallelism, and quantization to tune for speed, latency, concurrency, or cost.
- Model sandbox and API deployment: Offers sandbox APIs for testing and prototyping, then production API endpoints for deployed models, supporting a clearer path from evaluation to live use.
- Observability for model and infrastructure metrics: Tracks model API metrics, costs, and GPU/CPU utilization so teams can monitor deployment health and resource efficiency.
- Flexible deployment footprint: Supports scaling across multiple regions on Pipeshift Cloud or in a customer VPC, which is useful for teams that need geographic reach or infrastructure control.
Helpful Tips
- Validate SLA needs before vendor selection: For real-time inference platforms, define target metrics such as time-to-first-token, concurrency, uptime, and cold-start tolerance early, since these drive architecture and cost decisions.
- Check how much tuning is workload-specific: Pipeshift emphasizes workload-specific optimization, so buyers should test their exact model mix, token patterns, and traffic profile rather than rely on generic benchmark assumptions.
- Assess operational support requirements: The presence of Forward Deployed Engineers suggests the platform may be especially valuable for teams that want hands-on optimization support during pilot-to-production transitions.
- Review deployment model fit: If data locality, infrastructure control, or tenant isolation matters, compare cloud-hosted versus VPC deployment options and confirm how they align with internal platform standards.
- Treat compliance language carefully: The page mentions security practices and SOC2-related certifications, but procurement teams should still verify the exact scope, reports, and deployment-specific controls during diligence.
OpenClaw Skills
Pipeshift could fit well within an OpenClaw ecosystem as the production inference layer behind specialized agents and orchestration skills. A likely use case is an OpenClaw skill that routes requests to different Pipeshift-hosted models based on workload type, such as voice agents, document parsing, transcription, coding assistance, or customer support, while monitoring latency and fallback rules against defined SLAs. The source page does not confirm a native OpenClaw integration, so this should be viewed as a likely workflow pattern rather than a stated product capability.
This combination could be especially useful for AI product teams, platform engineers, and operations leaders who need agent reliability in production. OpenClaw agents could manage deployment policy, traffic routing, observability triage, and cost-aware model selection on top of Pipeshift’s dedicated inference stack. In practice, that could shift teams from manually babysitting model endpoints to running more automated inference operations with clearer control over performance, resilience, and deployment behavior.
Embed Code
Share this AI tool on your website or blog by copying and pasting the code below. The embedded widget will automatically update with the latest information.
<iframe src="https://aimyflow.com/ai/pipeshift-com/embed" width="100%" height="400" frameborder="0"></iframe>
Explore Similar Tools
Free AI Photo Editor: Edit & Generate Image Online | Pokecut
Pokecut is an AI photo editor that helps users remove backgrounds, enhance images, and generate visuals online, mainly for ecommerce sellers, marketers, and creators who need quick design-ready assets. It speeds up routine image production so visual teams can create polished content with less manual editing.
Roboflow: Computer vision tools for developers and enterprises
Roboflow is a computer vision platform that helps developers, machine learning engineers, and enterprises annotate data, train models, build workflows, and deploy vision AI for images, video, and real-time streams. In AI-driven operations, it can help computer vision and ML teams move faster from prototype to production by combining data labeling, model training, and deployment in one workflow.
Seedance 2.0
Seedance 2.0 is ByteDance's AI video generation model designed to create high-quality videos from prompts and multimodal inputs, mainly for creators, developers, and media teams. In the AI era, it helps visual content roles turn ideas into production-ready motion assets with far less manual editing effort.
Struct | Automate your on-call runbook
Struct is an AI on-call agent that investigates engineering alerts and bugs by analyzing logs, metrics, traces, and codebases, mainly for software engineers and SRE teams. In the AI era, it helps incident responders shorten triage time by delivering root-cause findings and suggested fixes directly in workflows.
GitMind Chat - Your Best AI Assistant
GitMind Chat is an AI assistant and chatbot platform that helps individuals and enterprises handle conversations, analysis, writing, coding, translation, customer service, and custom AI agent creation through prebuilt or configurable assistants. For roles such as marketers, analysts, support teams, educators, and developers, it can streamline repetitive knowledge work by combining chat, file and link inputs, image analysis, and contextual responses in one workflow.
GitPage AI Website Builder | GitPage
GitPage is an AI website builder that generates and deploys websites, online stores, and landing pages from a form, mainly for freelancers, agencies, startups, and businesses that want no-code site creation with code ownership. For web professionals and client-service teams, it can reduce manual setup and content drafting by automating page generation, blog content, and deployment to GitHub or GitLab Pages.
Rohan Mehta
Rohan Mehta is a personal website for a New York–based software engineer at OpenAI, outlining his background at Meta and as a YC-backed startup founder, and highlighting his creator role behind the Subway Time NYC transit app. For software engineers and technical hiring teams, this kind of concise profile helps AI-era talent evaluation by quickly surfacing relevant build, scale, and product experience.
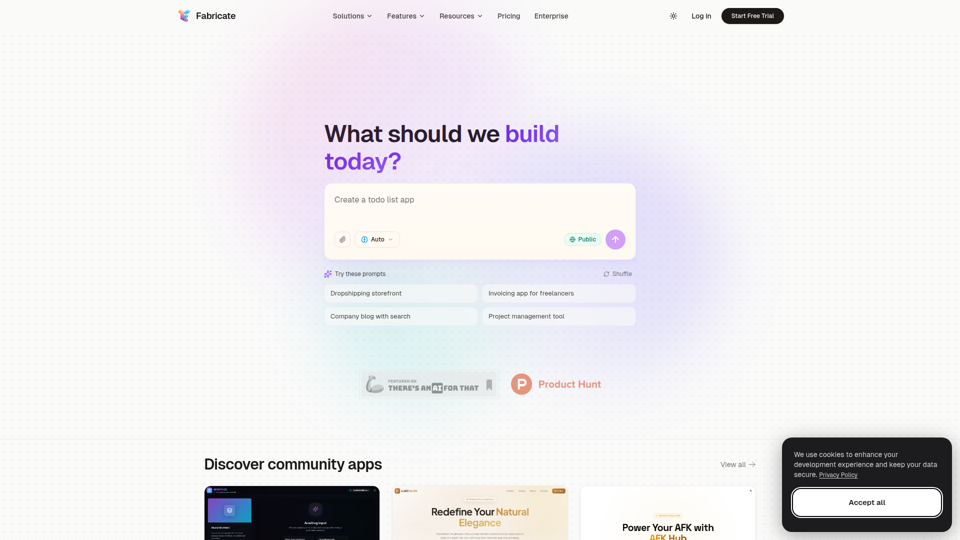
Fabricate - AI Full-Stack App Builder | Build Anything, Ship Faster
Fabricate is an AI full-stack app builder that helps users describe an app idea and generate production-ready web applications, mainly for founders, developers, designers, freelancers, agencies, and enterprises. In AI-assisted product development, it can help these teams move faster from concept to deployable React, TypeScript, and backend code with less manual setup.