
Nebius Token Factory Inference Service
Rate this Tool
Average Score
Total Votes
Select your score (1-10):
Detail Information
What
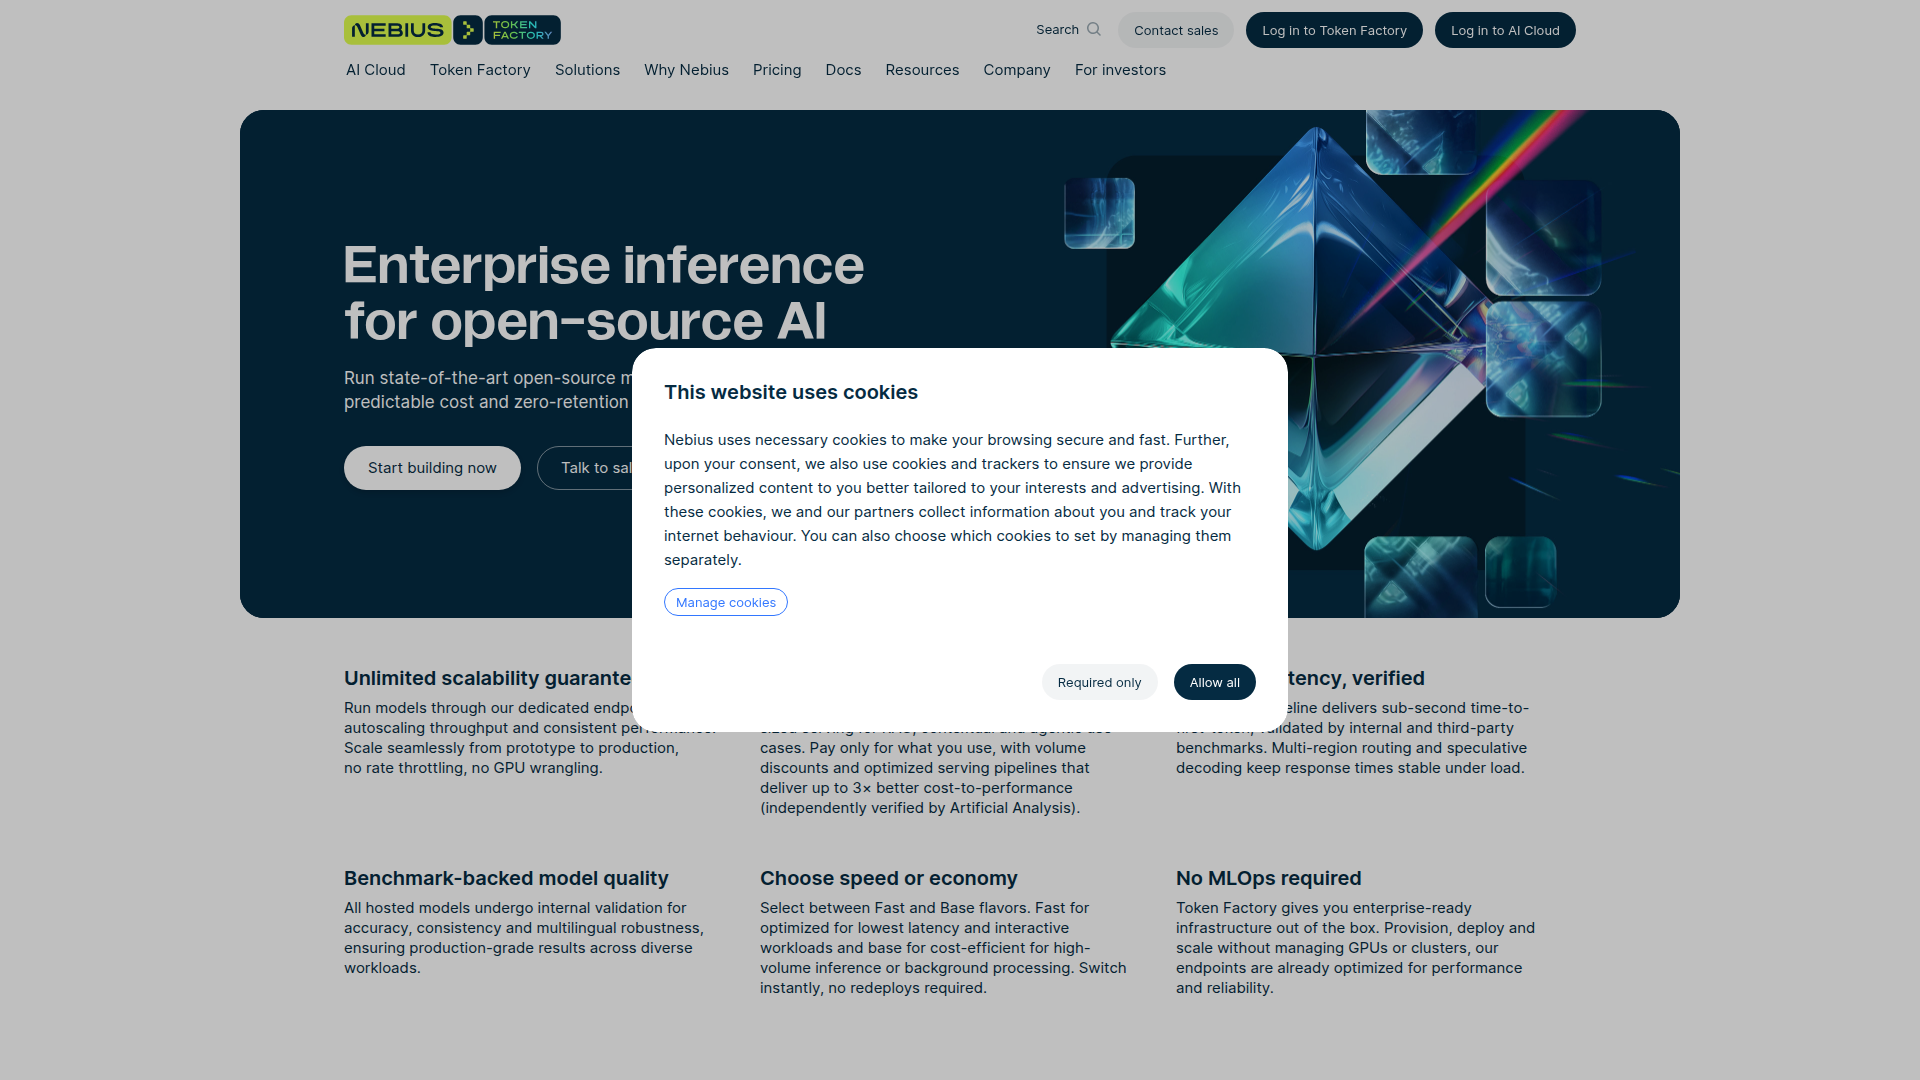
Nebius Token Factory Inference Service is an enterprise inference platform for running open-source AI models through hosted APIs and dedicated endpoints. It is aimed at teams that want production-grade model serving without managing GPUs, clusters, or other MLOps infrastructure.
The service appears positioned between developer-friendly model APIs and enterprise deployment infrastructure. Its core workflow is to let users test models in a playground or via an OpenAI-compatible API, then scale to dedicated endpoints with autoscaling, regional routing, throughput guarantees, and optional deployment of custom fine-tuned models.
Features
- Hosted open-source model inference: Provides access to a catalog of open-source models for reasoning, coding, dialogue, and multilingual workloads without self-hosting.
- Dedicated endpoints with autoscaling: Supports isolated production deployments with guaranteed throughput and scaling behavior for sustained or bursty workloads.
- Fast and Base performance tiers: Lets teams choose lower latency for interactive use cases or lower-cost throughput for batch and background jobs, with no redeploy required to switch.
- OpenAI-compatible API: Uses a familiar API pattern, which can reduce migration effort for teams already building against OpenAI-style chat completion interfaces.
- Custom model deployment: Supports uploading and hosting LoRA or fully fine-tuned models through the dashboard or API for teams that need tailored model behavior.
- Security and governance options: The page states zero-retention mode, RBAC, unified billing, regional deployment options, and enterprise support features such as SSO and SLA-backed capacity.
Helpful Tips
- Match tier to workload shape: Interactive assistants and agent flows are likely better suited to Fast, while large-scale background processing may fit Base more efficiently.
- Validate model choice by task, not only benchmark rank: The page lists several strong reasoning and coding models, but teams should test prompt format, context length, and structured output behavior against real workloads.
- Use dedicated endpoints for predictable production traffic: If latency consistency, isolation, or throughput guarantees matter, dedicated capacity is likely more appropriate than shared access.
- Clarify security and residency requirements early: The site mentions zero retention, compliance options, and EU/US regional deployment, so regulated teams should confirm the exact operating mode and contract terms needed.
- Plan for custom model lifecycle needs: Fine-tuned model hosting is available, but the page says broader post-training and distillation workflows are still forthcoming, which may affect long-term platform fit.
OpenClaw Skills
Within the OpenClaw ecosystem, Nebius Token Factory could likely serve as a model execution layer for inference-heavy skills and agents. Likely use cases include retrieval-augmented research agents, coding copilots, multilingual support workflows, document reasoning pipelines, and batch classification jobs that need access to large open-source models with controllable latency and cost.
OpenClaw agents could also be designed to route tasks across Nebius model tiers based on urgency, complexity, or budget. For example, an OpenClaw workflow might use Base endpoints for large-scale background summarization and Fast endpoints for live analyst copilots or customer-facing assistants. The page does not state a native OpenClaw integration, so this should be treated as an architectural inference rather than a confirmed product capability.
Embed Code
Share this AI tool on your website or blog by copying and pasting the code below. The embedded widget will automatically update with the latest information.
<iframe src="https://aimyflow.com/ai/nebius-com-services-studio-inference-service/embed" width="100%" height="400" frameborder="0"></iframe>
Explore Similar Tools
Free AI Photo Editor: Edit & Generate Image Online | Pokecut
Pokecut is an AI photo editor that helps users remove backgrounds, enhance images, and generate visuals online, mainly for ecommerce sellers, marketers, and creators who need quick design-ready assets. It speeds up routine image production so visual teams can create polished content with less manual editing.
Roboflow: Computer vision tools for developers and enterprises
Roboflow is a computer vision platform that helps developers, machine learning engineers, and enterprises annotate data, train models, build workflows, and deploy vision AI for images, video, and real-time streams. In AI-driven operations, it can help computer vision and ML teams move faster from prototype to production by combining data labeling, model training, and deployment in one workflow.
Seedance 2.0
Seedance 2.0 is ByteDance's AI video generation model designed to create high-quality videos from prompts and multimodal inputs, mainly for creators, developers, and media teams. In the AI era, it helps visual content roles turn ideas into production-ready motion assets with far less manual editing effort.
Struct | Automate your on-call runbook
Struct is an AI on-call agent that investigates engineering alerts and bugs by analyzing logs, metrics, traces, and codebases, mainly for software engineers and SRE teams. In the AI era, it helps incident responders shorten triage time by delivering root-cause findings and suggested fixes directly in workflows.
GitMind Chat - Your Best AI Assistant
GitMind Chat is an AI assistant and chatbot platform that helps individuals and enterprises handle conversations, analysis, writing, coding, translation, customer service, and custom AI agent creation through prebuilt or configurable assistants. For roles such as marketers, analysts, support teams, educators, and developers, it can streamline repetitive knowledge work by combining chat, file and link inputs, image analysis, and contextual responses in one workflow.
GitPage AI Website Builder | GitPage
GitPage is an AI website builder that generates and deploys websites, online stores, and landing pages from a form, mainly for freelancers, agencies, startups, and businesses that want no-code site creation with code ownership. For web professionals and client-service teams, it can reduce manual setup and content drafting by automating page generation, blog content, and deployment to GitHub or GitLab Pages.
Rohan Mehta
Rohan Mehta is a personal website for a New York–based software engineer at OpenAI, outlining his background at Meta and as a YC-backed startup founder, and highlighting his creator role behind the Subway Time NYC transit app. For software engineers and technical hiring teams, this kind of concise profile helps AI-era talent evaluation by quickly surfacing relevant build, scale, and product experience.
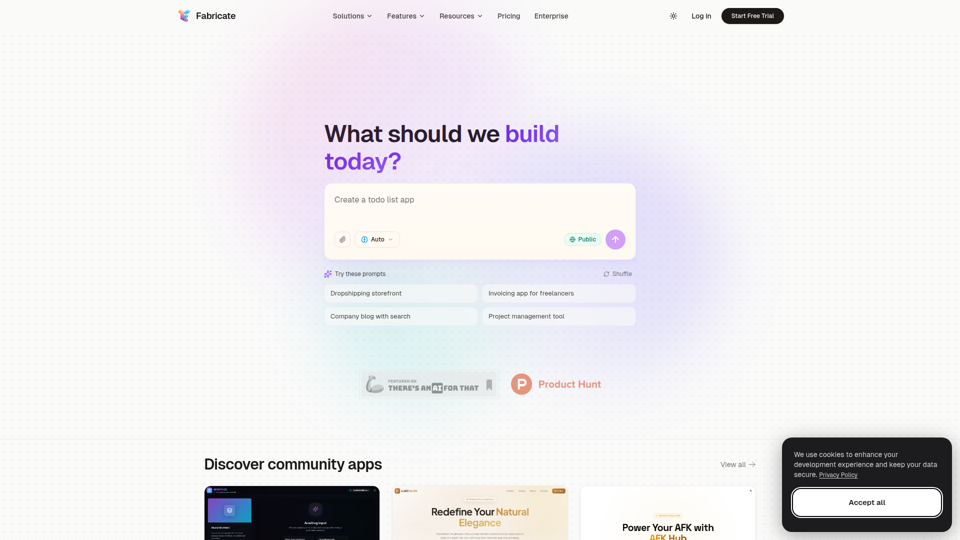
Fabricate - AI Full-Stack App Builder | Build Anything, Ship Faster
Fabricate is an AI full-stack app builder that helps users describe an app idea and generate production-ready web applications, mainly for founders, developers, designers, freelancers, agencies, and enterprises. In AI-assisted product development, it can help these teams move faster from concept to deployable React, TypeScript, and backend code with less manual setup.